Riseklix’s India AI Visibility Index 2026 found that all five recorded AI engines selected the same first-choice brand on 19 of 45 recommendation questions. That is 42.2%, and the figure comes from a single-day pilot collected on September 8, 2026.
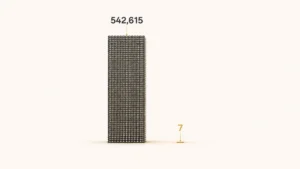
The study recorded 240 answers because the same 48-question bank was run across ChatGPT, Claude, Microsoft Copilot, Gemini and Perplexity. Only P01-P45 asked for recommendations, producing 225 recommendation answers. P46-P48 were descriptive regulated-consumer questions and were excluded from first-choice comparisons.
That denominator is the useful part. The study does not show that “AI engines agree 42% of the time.” It shows how often five recorded systems converged on one normalized first pick for this particular set of India-focused commercial questions.
Direct answer — How consistent were major AI engines when recommending brands for the same commercial questions in India?
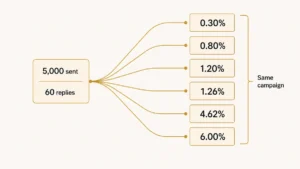
In Riseklix’s September 8 pilot, all five recorded engines chose the same normalized first-choice brand on 19 of 45 recommendation questions, or 42.2%. At least one engine differed on the other 26. IVRIS’s recalculation of the question-level table found ChatGPT and Gemini shared the same first pick on 28 of 45 questions, or 62.2%. This is a one-day consistency snapshot, not a stable ranking.
- Five-engine unanimous first-choice agreement occurred on 19 of 45 recommendation questions: 42.2%.
- The remaining 26 recommendation questions had at least one different first-choice brand.
- IVRIS calculated ChatGPT-Gemini first-choice overlap at 28 of 45 questions, or 62.2%.
- Four recommendation segments were unanimous on all three questions; seven had no unanimous question.
- The results came from one day, with unequal interface and search conditions across engines.
What the 240-answer pilot actually tested
Riseklix used 48 researcher-selected commercial questions across 16 broad segments. Fourteen segments used recommendation, comparison and scenario prompts. Essential Consumer Services used separate jobs, logistics and energy questions, while three regulated-consumer prompts were descriptive rather than purchase recommendations.
The five recorded systems generated one observation per question in the published register, giving 48 × 5 = 240 answers. For first-choice analysis, the denominator becomes 45 × 5 = 225 answers. The engines were not limited to a fixed brand panel: 56 of those 225 first choices fell outside the declared 100-brand reference panel.
The 42.2% result is narrower than general AI agreement
The formula is simple: 19 unanimous questions ÷ 45 recommendation questions × 100 = 42.22%, reported as 42.2%. The other 26 questions had at least one different first choice.
Pairwise overlap is a different measure. IVRIS calculation from the Riseklix India AI Visibility Index dataset: ChatGPT and Gemini matched first picks on 28 of 45 questions, or 62.2%. Across all ten pairs, the highest overlap was ChatGPT-Copilot at 38 of 45, or 84.4%; the lowest was ChatGPT-Perplexity at 26 of 45, or 57.8%.
This is also separate from mention share or citation share. IVRIS has previously explained why AI citations and brand mentions need separate denominators; a first-place recommendation is another distinct observation.
Consensus varied sharply by segment
Grouping the 45 recommendation questions by the segment labels in the published table produces a more useful picture than one overall percentage.
| Unanimous questions | Segments |
|---|---|
| 3 of 3 | Payments & Fintech; Telecom; Automotive & Mobility; Home & Personal Care FMCG |
| 2 of 3 | IT Services; Retail & E-commerce; Essential Consumer Services* |
| 1 of 3 | Food Delivery & QSR |
| 0 of 3 | Banking; Insurance; Fashion, Beauty & Jewellery; Travel & Hospitality; Food & Beverage FMCG; Construction Materials; Real Estate |
IVRIS calculation from the Riseklix India AI Visibility Index dataset. *P43-P45 cover three different essential-services tasks, so that segment should not be read as three interchangeable category prompts.
Fashion, Beauty & Jewellery was the most fragmented segment by a simple first-pick count: each of its three questions produced three distinct first-choice brands across the five engines. That does not make the category inherently unstable; it describes three questions on one collection date.
The one-day design sets a hard evidence boundary
Riseklix says the questions were submitted in batches within sessions and each was instructed to be treated independently, but that does not make the answers statistically independent. Search or web grounding was not standardized, and there were no repeated fresh-session runs across multiple days.
The interface conditions were also uneven. ChatGPT was run on the ChatGPT website, but the exact displayed model, account status and search settings were not independently verified. Claude was recorded through an Antigravity IDE environment rather than a standardized consumer website interface. Exact routing and settings for Copilot, Gemini and Perplexity were not established by the web edition. An exact device, signed-in state and controlled geographic setting are therefore not available as common controls.
The web edition is not peer reviewed, and its normalized records are not authenticated exports of the original sessions. It does not establish which recommendation was “best,” why a model chose it, or whether a recommendation would lead to traffic, purchases, leads or revenue.
What marketers can reasonably take from the benchmark
The clean takeaway is operational: one engine is not a reliable stand-in for all five. Even ChatGPT and Gemini, the pair most likely to be compared in search results, shared the same first pick on only 62.2% of these 45 questions in IVRIS’s calculation.
For measurement, the useful unit is a frozen buyer question tracked by engine and date. That matches IVRIS’s view that AI visibility metrics need their denominator and collection conditions attached. Teams can compare AI-search visibility and GEO platforms for repeated tracking, but this pilot tested no optimization tactic.
A stronger benchmark would rerun the same questions in fresh sessions across multiple days, record model and retrieval settings, preserve source evidence and compare how often the first-choice result persists. Until then, 42.2% is best treated as a dated cross-engine consistency observation, not an India-wide AI recommendation rate.
Frequently Asked Questions
All five recorded engines had the same normalized first-choice brand on 19 of 45 recommendation questions. That is 42.2%. The denominator is recommendation questions, not all 240 answers and not every possible pair of engines.
No. The 42.2% figure requires all five engines to select the same first-choice brand. IVRIS calculated ChatGPT-Gemini first-choice overlap separately at 28 of 45 recommendation questions, or 62.2%, for this one-day dataset.
The study used 48 questions across five engines, giving 240 recorded answers. Only 45 questions requested recommendations. The final three were descriptive regulated-consumer prompts, so Riseklix excluded them from first-choice agreement analysis.
No. It is a September 8, 2026 snapshot without repeated fresh-session testing across days. Model routing, retrieval state, prompt wording, location and session context can change outputs, so the recorded first choices should not be treated as permanent rankings.