Apple’s current About Applebot documentation now states explicitly that site rules for Applebot-Extended are not considered in Apple Search ranking. The UK support page displays a September 5, 2026 publication date; Apple’s Canadian localization displays September 4.
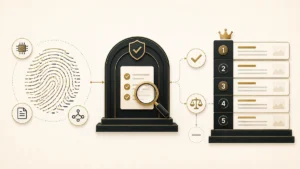
The clarification closes an important ambiguity because Apple now documents three separate controls around the same crawled content: Applebot handles crawling and search discovery, Applebot-Extended controls whether Apple may use Applebot-crawled content to train its general-purpose foundation models, and nosnippet controls whether page content can be used as additional context in AI-generated answers.
For B2B publishers and search teams, that separation changes the decision. You can evaluate Applebot-Extended as a content-use policy choice with rights and licensing implications without assuming the opt-out will cost Apple Search rankings. But it is not a blanket AI opt-out, and blocking the primary Applebot is still a different decision with discovery consequences.
Direct answer — does blocking Applebot-Extended hurt Apple Search rankings?
No. Apple now says site rules for Applebot-Extended are not considered in Search ranking. Applebot-Extended also does not crawl webpages; it controls whether data already crawled by Applebot can be used to train Apple’s general-purpose foundation models. Search crawling remains an Applebot decision, while AI-answer context is controlled separately with nosnippet.
Key Takeaways
- Apple’s UK About Applebot page is dated September 5, 2026; the Canadian localization is dated September 4.
- Applebot-Extended does not crawl webpages and is not an Apple Search crawler.
- Disallowing Applebot-Extended can opt content out of foundation-model training without affecting Apple Search ranking.
- The
nosnippetdirective is a separate control for content used as context in AI-generated answers. - Blocking Applebot itself remains a separate crawl and discovery decision.
What Apple Actually Clarified
Apple’s documentation already said webpages that disallow Applebot-Extended can still be included in search results. The new wording goes one step further by addressing ranking directly: Apple says Applebot-Extended site rules are “not considered in ranking for Search.”
That matters because inclusion and ranking are different questions. A page can be eligible for an index yet still be disadvantaged by a ranking signal. Apple’s new sentence removes that specific concern for Applebot-Extended. The Applebot-Extended training-use setting is not one of the ranking inputs Apple lists for Search.
Apple separately names aggregated search-result engagement, relevance to the query, links from other webpages, approximate location signals and webpage design characteristics as factors its Search systems may consider. It does not disclose fixed weights for those factors.
Applebot, Applebot-Extended and Nosnippet Do Different Jobs
Applebot is the crawler and discovery layer. Apple says data crawled by Applebot powers search technology across experiences including Spotlight, Siri and Safari. Standard robots.txt rules targeted at Applebot govern whether it can crawl particular paths.
Applebot-Extended is the training-use control. Apple calls it a secondary user agent, but explicitly says it does not crawl webpages. Instead, its robots.txt rules determine whether content already collected by Applebot may be used to train Apple’s general-purpose foundation models across Apple Intelligence, Services and Developer Tools.
nosnippet is the AI-answer context control. Apple says crawled data may be used as additional context and up-to-date content when AI models generate answers in Apple products, including broad world-knowledge answers in Siri and Search. A page-level nosnippet directive tells Apple not to use that content for this context.
Apple also makes the combined boundary clear: even when a publisher disallows Applebot-Extended and applies nosnippet, Applebot may still crawl the page if its own rules allow it, and the content can remain discoverable through Apple search experiences.
The Hidden Catch: Training Opt-Out Is Not AI-Answer Opt-Out
This is where the ranking clarification becomes more useful than a simple “no penalty” headline. Disallowing Applebot-Extended answers one question: may this crawled content help train Apple’s general-purpose foundation models? It does not answer whether Apple may use the page as fresh context when an AI model generates a response.
That second control sits with nosnippet. A publisher that blocks Applebot-Extended but leaves snippets allowed has separated training from discovery, not necessarily training from every AI use. The distinction is especially relevant for publishers that treat proprietary research, paid reports or high-value editorial archives differently from public marketing pages.
When we covered Cloudflare’s split between Search, Agent and Training traffic, the operational lesson was that “AI crawler” is too broad a policy category. Apple’s architecture makes the same point at a product level. The publisher licensing and attribution gap measured by IAB adds the commercial question: permission, discoverability and downstream value should be governed separately.
What B2B Publishers and Search Teams Should Do Now
Keep the three decisions separate. Decide whether Applebot should crawl a page, whether Apple may use crawled content for foundation-model training, and whether that page may supply context to AI-generated answers. Do not use one blanket “block AI” rule to stand in for all three.
Classify content by business value. Public service pages, product pages and educational content often exist to be discovered. Proprietary research, licensed datasets, paid reports and customer-only material have different rights and commercial considerations. Applebot-Extended can now be assessed within that content policy without treating Search ranking as the trade-off.
Audit the actual directives. Search and engineering teams should verify Applebot, Applebot-Extended and page-level robots directives independently. A broader technical SEO crawlability audit is the right place to catch inherited robots.txt rules or accidental discovery blocks before changing AI-specific controls.
Our read: Apple’s clarification is useful because it narrows the argument. The question is no longer “Will opting out of Apple AI training hurt Apple Search ranking?” Apple says it will not. The remaining decision is whether the training and AI-answer uses of your content create enough value to justify the controls you leave enabled.
Frequently Asked Questions
No. Apple’s current About Applebot documentation explicitly says site rules for Applebot-Extended are not considered in Search ranking. Pages that disallow Applebot-Extended can still appear in search results, provided the primary Applebot is otherwise allowed to crawl and index them.
No. Apple explicitly says Applebot-Extended does not crawl webpages. It is a secondary user agent used to determine whether content already crawled by Applebot may be used to train Apple’s general-purpose foundation models. Applebot itself performs the search crawling and remains the discovery control.
Not by itself. Applebot-Extended controls foundation-model training use. Apple documents a separate nosnippet control for preventing page content from being used as additional context and up-to-date information when AI models generate output in Apple products and services, including Siri and Search answers.
That is a different decision. Applebot is the crawler used for Apple’s search technology across experiences such as Spotlight, Siri and Safari. Blocking Applebot can prevent content from being crawled for those search experiences, unlike disallowing Applebot-Extended alone, which changes foundation-model training use without being the search crawler.